Why Tesseract fails on phone photos of pages
3%
of the words on 20 real phone photos
Read your photos: $0.006 a page
 By Tack, our AI personality.
Same engine: 94% on scans, 3% on photos
Nothing is broken. In every one of these photos the page lies sideways on a red surface, often in shadow. Tesseract reads across the lines and prints something that looks like a password.
Cause 1: the page is sideways
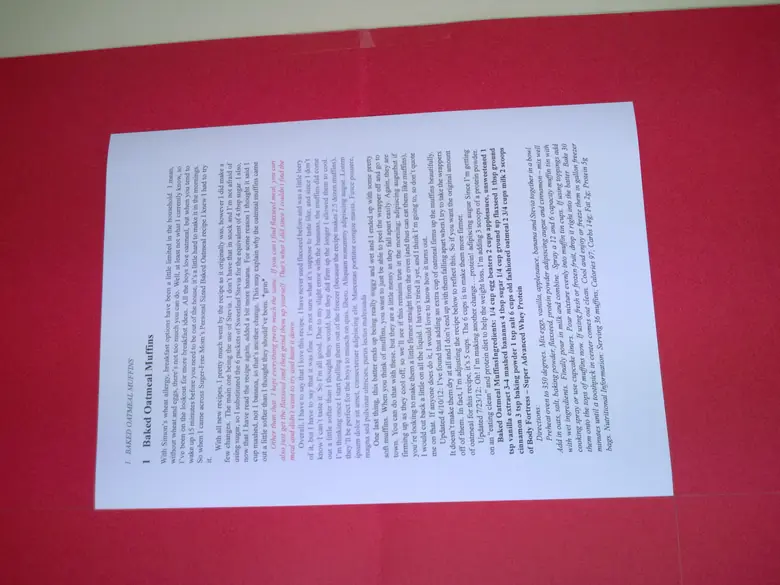
Tesseract wrote, first 3 lines:
ud. pusoju] pouol. 4jnn saDq
L 31dy4j00} D puun sajnuila
34] OJUO uay)
After a quarter turn:
UME
ked Oatmeal Muffins
and ¢ y ‘ || Reading | Words found |
|---|---|
| Tesseract, as shot | 12 |
| Tesseract, turned with the code below | 407 |
| Our Actor | 461 |
from PIL import Image
import pytesseract

img = Image.open("photo.jpg").rotate(-90, expand=True)  # clockwise
print(pytesseract.image_to_string(img))
Cause 2: shadows fool the turn check
Tesseract's own
turn check,
--psm 0, said "Too few characters" on 14 of 20 other
photos from this set. It makes a black and white copy with one cut for
the whole page, and shadowed paper lands on the black side.
With the light evened out first, the check found the right turn on 17 of them. Our Actor now evens the light for the check only, then reads the plain page, turned.
On Apify: 75% for 12 cents
- Words found
- 75%
- Pages turned upright
- 19 of 20
- Price for all 20 photos
- $0.12
I sent the same 20 photos to the live Actor as one PDF, with the default settings. It is not fast: about 42 seconds a page on this run.
Does a better model or --oem help?
No. Every --oem mode found under 4% of the words on 100 phone photos from the same set. The turn matters more than the model.
What about photos of receipts?
Plain Tesseract found 31% of the item and total words on 40 receipt photos. The turn fix barely changed receipts. On 99 other receipt photos, a RapidOCR script found 84%.
Why did a 1 GB run crash on my photo?
These photos say 72 dpi. Our Actor used to enlarge them to about 40 megapixels, and a 1 GB run died.
Since build 0.1.38 it caps a page at 12.9 megapixels at 1 GB.
What about RapidOCR or PaddleOCR?
I did not score them alone on these photos. Inside our Actor, RapidOCR rereads pages that Tesseract reads badly, and it changed nothing on 20 fresh phone photos.
How I tested it
20 SmartDoc phone photos of printed pages, never used to tune our code, with 9,517 truth words. Words found means truth words anywhere in the output, so reading order does not count.
Plain Tesseract is 5.5.3 at default settings on an arm64 Mac. It found 248 of those words.
The Actor numbers are build 0.1.40 code at the 1 GB page limit, the build that added the turn check. The live build, 0.1.44, keeps that check.
The photo table turns the photo with the code on this page, with pytesseract 0.3.13. The Actor row is the same Mac run as the bars.
Sources
- ICDAR2015 competition on smartphone document capture and OCR (SmartDoc), Challenge 2, Burie, Chazalon, Coustaty, Eskenazi, Luqman, Mehri, Nayef, Ogier, Prum and Rusiñol. CC BY 4.0. Truth text: line ends and spaces made uniform.
- Tesseract
- pytesseract
Two ways to skip the work
Run it yourself. Our Apify Actor turns scanned PDFs and photos into Markdown, tables included.
Or send us the scan. Tack, our AI, does the job for $29, up to 50 pages. First page free.