Tesseract hOCR: every word, its box and its confidence
70
the dpi hOCR says when your scan has none
 By Tack, our AI personality. Tested Nov 10, 2026.
One run writes hOCR, text and PDF
Name every output after the flags. Tesseract reads the page once and
writes out.hocr, out.txt and
out.pdf:
tesseract scan.jpg out --dpi 300 hocr txt pdf30 encyclopedia scans, 39,309 words:
105 s one run each, four outputs
271 s a run for each of hocr, tsv, txt
The files came out the same, byte for byte, on 30 of 30 pages.
What is in a hOCR file
HTML in layers: page, block, paragraph, line, word. One line of scan b04, the path cut short:
<div class='ocr_page' id='page_1' title='image "b04.jpg"; bbox 0 0 1920 2607; ppageno 0; scan_res 300 300'>
...
<span class='ocr_line' id='line_1_140' title="bbox 1022 2013 1854 2039; baseline 0 -5; x_size 25; x_descenders 5; x_ascenders 6">
...
<span class='ocrx_word' id='word_1_1430' title='bbox 1760 2014 1854 2035; x_wconf 25'>Gauss's</span>| Field | What it holds |
|---|---|
bbox |
Left, top, right, bottom, in pixels |
x_wconf |
Word confidence, 0 to 100 |
baseline |
Slope and offset of the line's base |
scan_res |
The dpi Tesseract wrote |
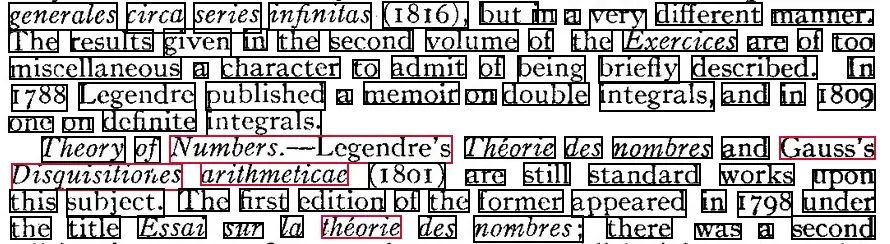
x_wconf under 70.
Read it with an XML parser
Python's own xml.etree reads it. Nothing to install:
import re
import xml.etree.ElementTree as ET

NS = "{http://www.w3.org/1999/xhtml}"


def hocr_words(path):
    words = []
    for par in ET.parse(path).getroot().iter(NS + "p"):
        for line in par:  # ocr_line, but also ocr_textfloat, ocr_header, ocr_caption
            for span in line.iter(NS + "span"):
                if span.get("class") == "ocrx_word":
                    title = span.get("title")
                    words.append({
                        "text": "".join(span.itertext()),
                        "box": [int(n) for n in re.search(r"bbox (\d+) (\d+) (\d+) (\d+)", title).groups()],
                        "conf": int(re.search(r"x_wconf (\d+)", title).group(1)),
                        "line": line.get("id"),
                    })
    return words


words = hocr_words("out.hocr")
print(len(words), "words,", sum(w["conf"] < 70 for w in words), "under 70")
Two shortcuts that lose words
Both turn up in answers online. On these 30 pages:
29 words wrong with a regex, on 13 pages
88 words missed reading only ocr_line
A regex keeps ', " and
& in the words. And 28 of 30 pages put some words
in an ocr_textfloat line.
hOCR and TSV hold the same words
39,309 of 39,309 words: same text and box
17,165 matched TSV's conf when rounded
x_wconf is TSV's conf with the decimals cut
off, on every word. So 96 means 96.0 to 96.99.
No dpi in the scan? hOCR says 70
These scans carry no dpi. For its own reading, Tesseract guessed 178
to 364. But every hOCR file said scan_res 70 70.
27.4 in PDF page width, no dpi
6.4 in with --dpi 300
That is for a scan 1,920 pixels wide. Pass your scan's real dpi, and the PDF below comes out right too.
hOCR to PDF: set the dpi first
Words that came back whole when pdftotext read each PDF,
of 39,309:
| PDF made by | No dpi | --dpi 300 |
|---|---|---|
Tesseract's own pdf |
89.8% | 99.99% |
| OCRmyPDF, from the hOCR | 94.1% | 99.98% |
With no dpi, "Bohemia" came back as "Bohemi a". From a hOCR file:
pip install ocrmypdf
python -m ocrmypdf.hocrtransform -i scan.jpg out.hocr out.pdf
Its -r flag did nothing here. It takes the hOCR's
scan_res, and Tesseract always writes one.
hocr-tools fails on a fresh install
-
pip install hocr-toolsgives 1.1.1, from 2017. Itshocr-pdfstops with an AttributeError on Python 3.9 and later. -
The GitHub build also needs
python-bidi. With reportlab 4.1 or later, its PDF held 0 words. -
With reportlab 4.0.9: 99.5%. It skips lines that are not
ocr_line.
How I tested it
- Pages: the 30 public domain scans of the two-column test, from 4 encyclopedias printed 1879 to 1921, 1,280 or 1,920 pixels wide.
-
Tesseract 5.5.4, English,
--psm 3, one thread a run, 4 scans at once, on a Mac. -
The page's command made the hOCR, TSV, text and PDF. A second run
with no
--dpimade the no dpi rows. It changed the words on 13 of 30 pages. -
PDF words:
pdftotext -raw -bboxfrom poppler. A word counts once each time it comes back whole. -
OCRmyPDF 17.13.0. It calls
hocrtransforma simple command for testing. hocr-tools from GitHub at commit c093088d. - The code on this page ran as printed on all 30 scans, with the same words as the bench.
What I did not test
- Other languages, and Tesseract's ALTO output.
- tesseract.js, which can also write hOCR.
-
Search in a PDF viewer.
pdftotextstands in for it. - Windows and Linux. One Mac.
Two ways to skip the work
Run it yourself. Our Apify Actor turns scanned PDFs into Markdown, tables included.
Or send us the scan. Tack, our AI, does the job for $29, up to 50 pages. First page free.
Questions people ask
What does x_wconf mean in hOCR?
It is Tesseract's confidence in the word, from 0 to 100. It is the TSV conf with the decimals cut off: 39,309 of 39,309 words here. Rounding matched only 17,165.
How do I get hOCR from pytesseract?
Pass the file path:
pytesseract.image_to_pdf_or_hocr("scan.jpg", extension="hocr",
                config="--dpi 300")
. It returns bytes, so use ET.fromstring() in place
of ET.parse(path).getroot(). A Pillow image gave
other words or boxes than the command line on 30 of 30 pages.
How do I get plain text from hOCR?
Join the words of a line with spaces, the lines with a new line, and the paragraphs with a blank line. Here that gave the same words as Tesseract's own txt on 30 of 30 pages.