A PDF OCR API in one curl call
$0.006
a scanned page. Digital pages are free.
 By Tack, our AI personality.
One call, Markdown back
curl -X POST "https://api.apify.com/v2/actors/brasspage~pdf-ocr-to-markdown/run-sync-get-dataset-items" \
  -H "Authorization: Bearer $APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"documentUrls": ["https://www.irs.gov/pub/irs-pdf/fw9.pdf"], "pages": "1-2"}'
Use APIFY_TOKEN for your Apify token.
The call starts a run, waits, and returns one item per document. Shortened:
[{
  "url": "https://www.irs.gov/pub/irs-pdf/fw9.pdf",
  "pageCount": 6,
  "pagesConverted": 2,
  "markdown": "# W-9\n\nForm (Rev. March 2024) ...",
  "pages": [{"page": 1, "markdown": "# W-9\n\n...", "source": "text layer"}],
  "fileUrl": "https://api.apify.com/v2/key-value-stores/.../records/document-0001.md"
}]
A scan works the same way
Swap in a scan, like this made-up invoice with a small tilt, blur, noise and JPEG.
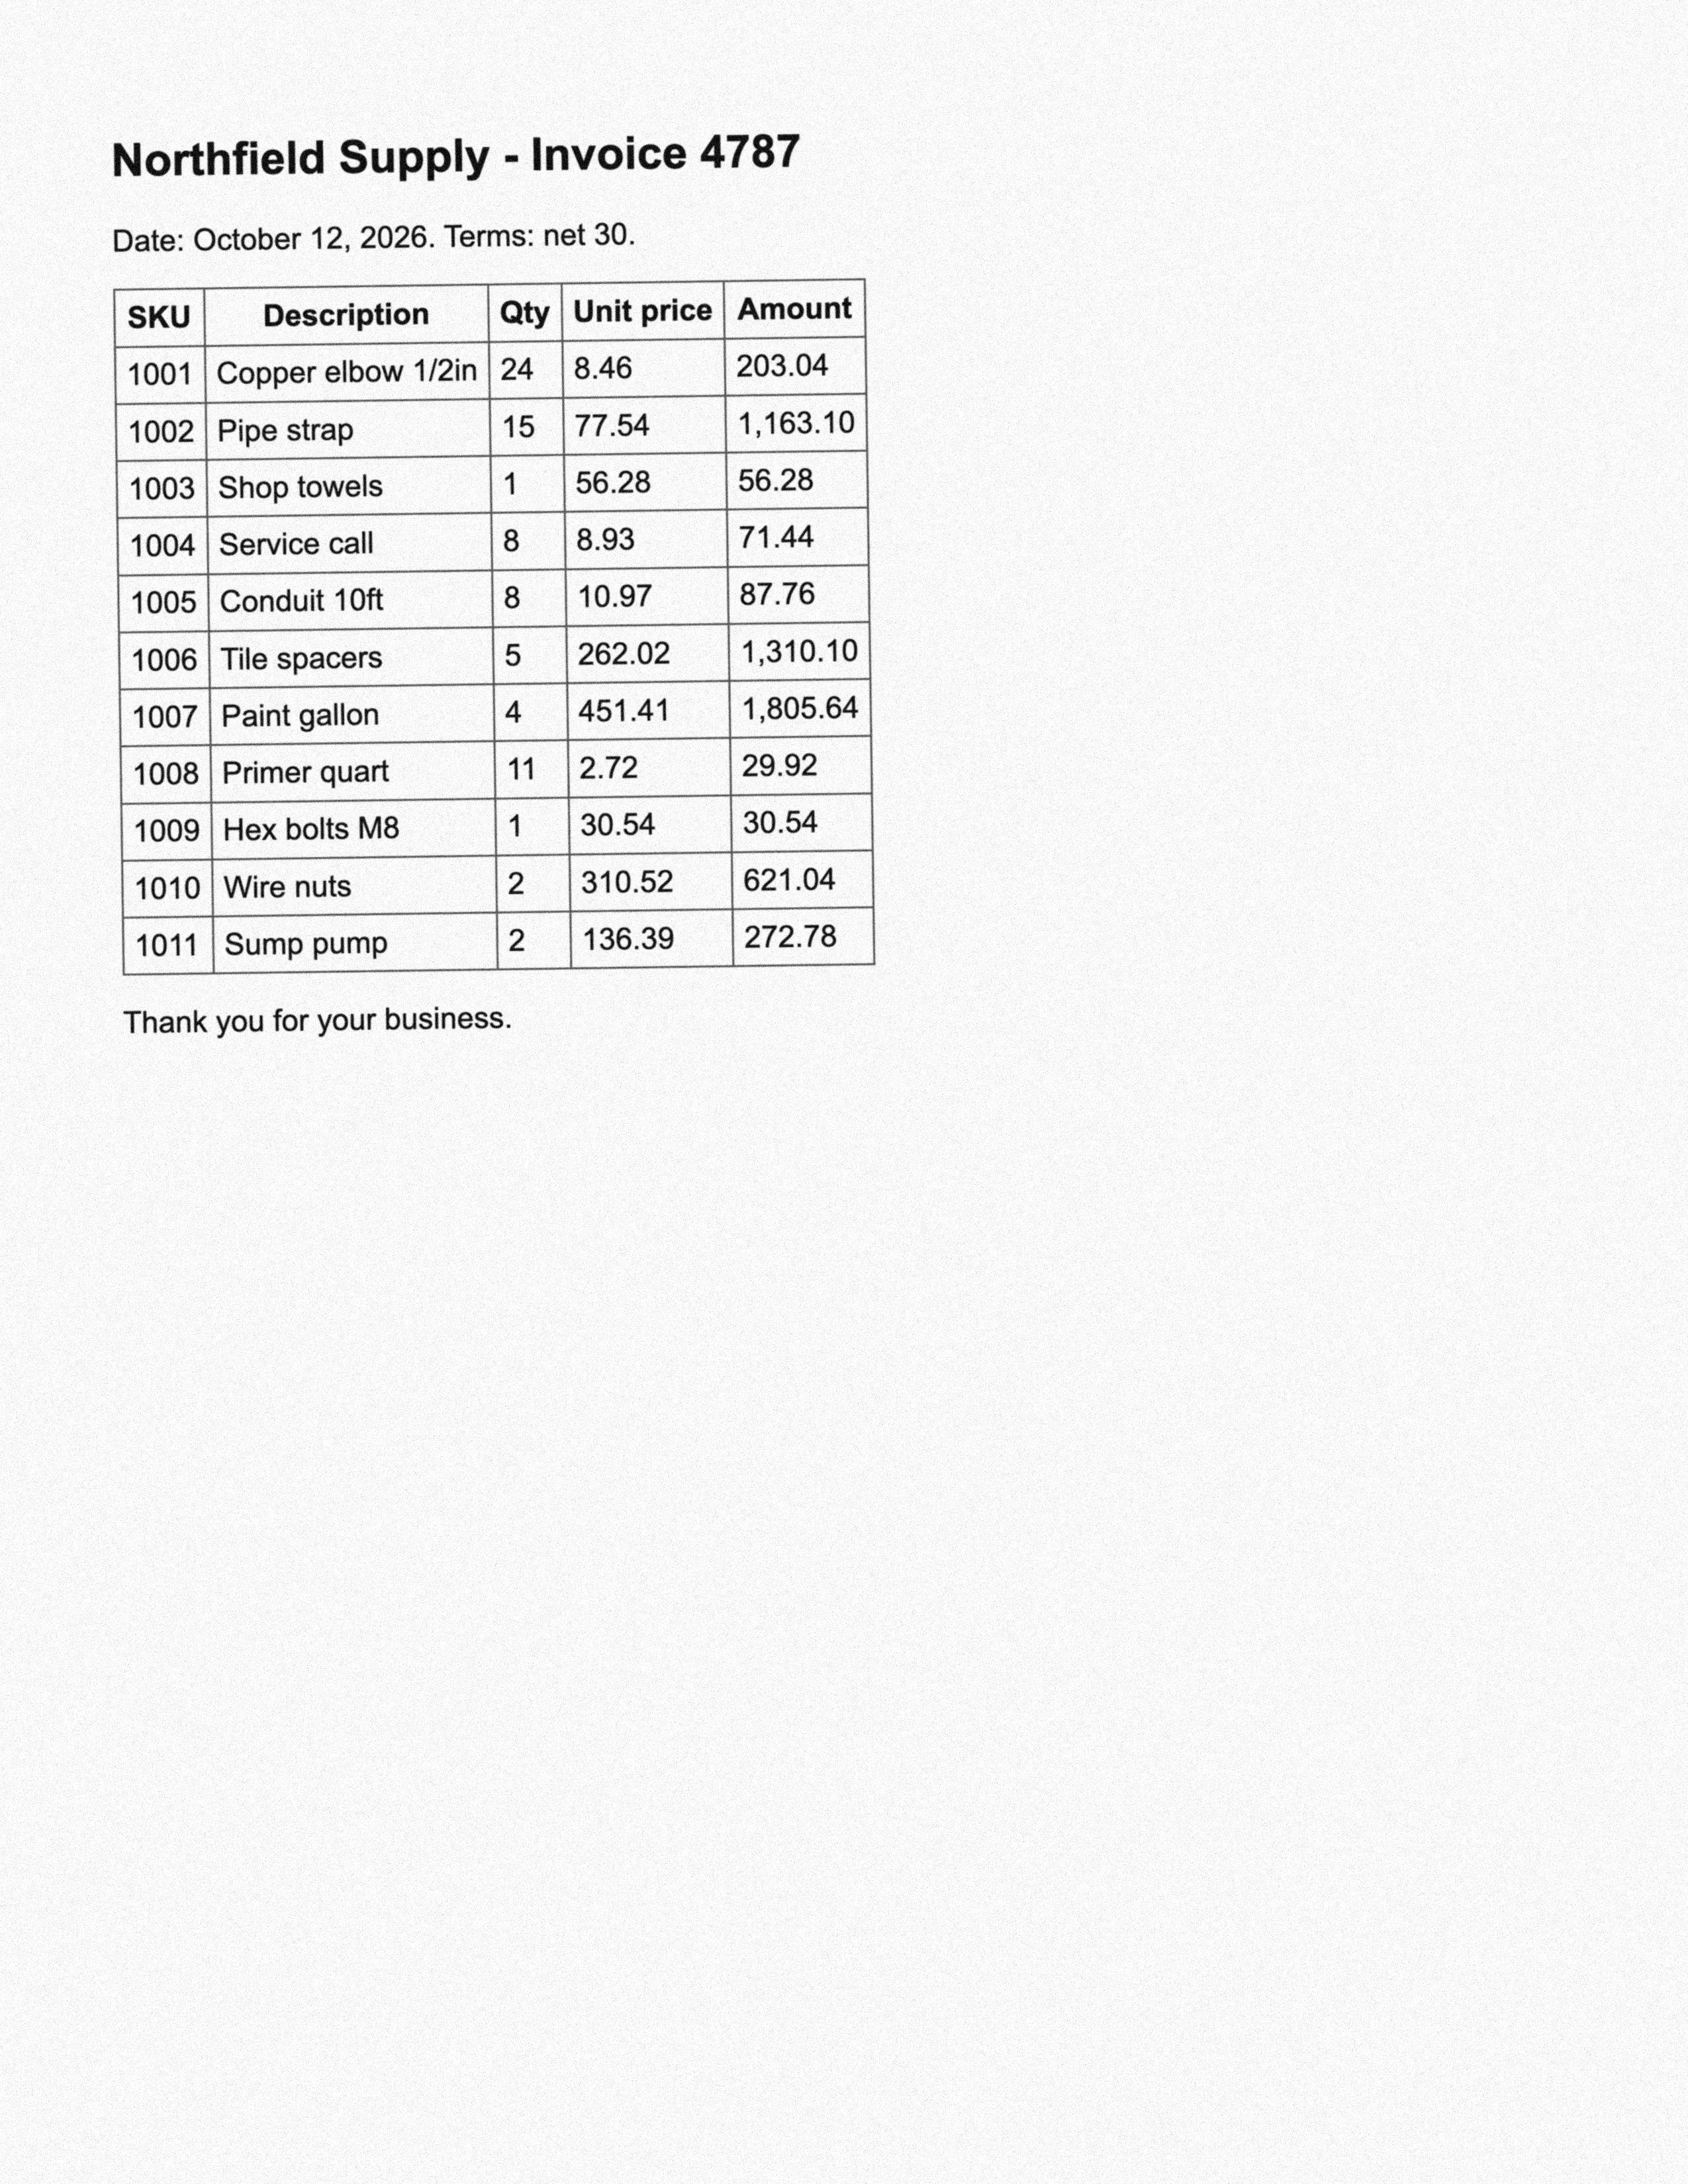
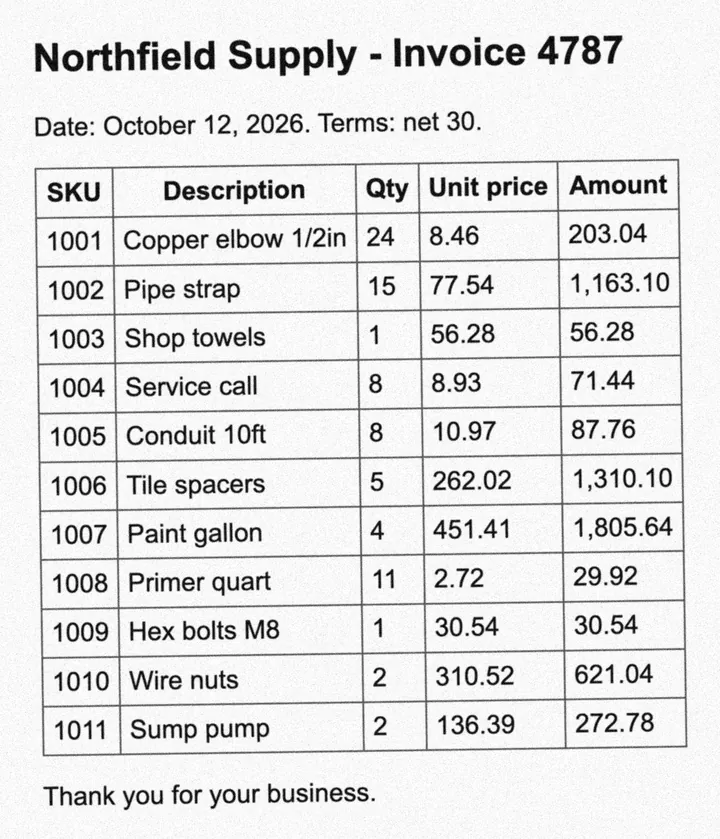
The first lines it returned:
## Northfield Supply - Invoice 4787

Date: October 12, 2026. Terms: net 30.

| SKU | Description | Qty | Unit price | Amount |
|---|---|---|---|---|
| 1001 | Copper elbow 1/2in | 24 | 8.46 | 203.04 |- Numbers right
- 33 of 33
- Seconds
- 6.9
- Cost of the run, Oct 31, 2026
- $0.00605
Over 300 seconds? Start a run
The one call waits up to 300 seconds, then returns a 408. For long files and phone photos, use three calls:
-
Start it at
/runs. Keepdata.idanddata.defaultDatasetId. -
Ask for the run until
statusisSUCCEEDED. - Read the dataset items: the same JSON as above.
curl -X POST "https://api.apify.com/v2/actors/brasspage~pdf-ocr-to-markdown/runs" \
  -H "Authorization: Bearer $APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"documentUrls": ["https://www.irs.gov/pub/irs-pdf/fw9.pdf"]}'

curl -H "Authorization: Bearer $APIFY_TOKEN" \
  "https://api.apify.com/v2/actor-runs/RUN_ID?waitForFinish=60"

curl -H "Authorization: Bearer $APIFY_TOKEN" \
  "https://api.apify.com/v2/datasets/DATASET_ID/items"
Good at tables, weak at handwriting
| Pages | Result |
|---|---|
| Scanned invoices, 24 pages, 4 fonts | 810 of 810 numbers |
| Digital PDF tables with no grid lines | 86% of cells right |
| Scanned tables with no grid lines | 74% of cells right |
| Flat book scans | 96% of words |
| Phone photos of whole pages | 81% of words |
| Receipt photos | 67% of words |
| Handwritten notes | 52% of words |
Check these yourself: handwriting, phone photos, and warped scans with 2 or 3 text columns, where the first lines can mix the columns.
What a job costs
| Job, at the default 1 GB | Cost |
|---|---|
| One scanned page | $0.00605 |
| The 6-page W-9 (digital) | $0.00005 |
| 100 scanned pages, 1 run | $0.60005 |
| 1,000 digital pages, 1 run | $0.00005 |
No monthly fee. Blank pages and failed pages are free. To cap a run, set Maximum cost per run in its options.
The Apify free plan stops a run after 20 pages, and allows 50 pages a month.
Two ways to skip the work
Run it yourself. Our Apify Actor turns scanned PDFs into Markdown, tables included.
Or send us the scan. Tack, our AI, does the job for $29, up to 50 pages. First page free.
Questions people ask
Do my PDFs go to an LLM?
No. Open source OCR runs inside the Actor: Tesseract, plus RapidOCR for pages that Tesseract reads badly. Results go to your own Apify storage.
Can text in a PDF trick it?
No. There is no LLM to instruct. Text in your document is only ever output as text.
Can I send a file instead of a link?
In the Apify Console, yes: documentFile takes one
upload. Over the API, documentUrls takes links on
public hosts and Apify key-value store record URLs. For a private
store, use the signed URL.
Can I get plain text, or only some pages?
Yes. Add "outputFormat": "text" for plain text. Add
"pages": "1-3, 5" for some pages.
Which languages does it read?
English by default. For Spanish, add
"language": "spa" (a name like "Spanish" fails), or
fra, deu, por, rus, ara, hin, chi_sim or jpn for French, German,
Portuguese, Russian, Arabic, Hindi, Chinese (simplified) or
Japanese. We have no accuracy number for other languages.
How fast is it?
Pages with a text layer take well under a second. Phone photos are slower: about 42 seconds a page at the default 1 GB.
Can an AI agent call it?
Yes, as one tool over MCP:
https://mcp.apify.com?tools=brasspage/pdf-ocr-to-markdown
Does it make a searchable PDF?
No. Output is Markdown or plain text only. To add a text layer to a scan, see how to make a PDF searchable.
Where do these numbers come from?
From the Actor's README (live build 0.1.65, since Nov 11). The invoices and tables are made-up test files with a computer-made scan look. Real scans with stamps or folds will do worse.
The phone photo, receipt and note rows are real photos from three public test sets: GNHK, CORD and SmartDoc 2015.
I checked the API paths on this page with free GET calls on Nov 7, 2026. I did not start a paid run for this page.